
Updated September 21, 2026. Start with the weekly checkup, use the workbook to investigate what fails, and bring in help when the fix reaches across your site.
Jump to the bonus AI-search checks for bot access, readable content, citations and AI-assisted auditing.
Technical SEO can be one of the highest-leverage areas of SEO to focus on, but sometimes it can be a total distraction. The distinction is understanding when it’s a high-priority project to work on for your business.
You know they’re there – lurking technical SEO problems on your site that you want to squash like a bug. Where are they though? Which are the most important? Where do you start?
Start with the pages that bring you customers. Can search engines reach them, see the important content, choose the right URL, and send people to a working page? Then make sure you can measure what happens next.
The target of this guide is for marketers and site owners who are somewhat already familiar with what SEO is, but need clarity on what to focus on.
There are hundreds of items to go through when doing an SEO audit or planning for the next 6 months. But there are a few high-level items that can really mess with your site. I’ve outlined some of the top items here.
I chose these because they are both crucial to the health of your site, and also quick to diagnose. The complexity of fixing them is another issue – that depends on the size of your site and the depth of the problem.
This is not a guide to fix all of your problems, just a starting point. The free workbook takes you further, with 48 beginner and intermediate checks, evidence fields, and a research compendium. There are also prompts and reusable AI skills for turning your findings into something a developer can actually use.
Six worked examples + editable templates. A short form unlocks the download.
The 22-Minute Technical SEO Top 10 Quick Priority List
Let’s do a quick run-through of the top 10. After you get good at checking these, you could in theory run through this in 22 minutes flat, once a week.
That assumes you already have access to Search Console and analytics, plus a recent crawl. First-time setup, waiting for tests, and fixing problems take longer. If your site is down, please abandon the stopwatch.
| Check | What you’re looking for | Minutes |
|---|---|---|
| 1. Robots.txt and access | An accidental block on important public pages | 2 |
| 2. Priority-page indexing | Unexpected indexing or canonical changes | 3 |
| 3. XML sitemap | A broken sitemap or missing important section | 1 |
| 4. Meta robots and headers | Accidental noindex on a key template | 2 |
| 5. Analytics events | Missing or duplicate page views and lead events | 2 |
| 6. Page Indexing and Crawl Stats | New problems affecting valuable pages | 3 |
| 7. Manual Actions and Security Issues | A reported action or security problem | 1 |
| 8. Internal links and redirects | Broken paths in your most important journeys | 3 |
| 9. Mobile page experience | Hidden content, unusable forms or new slowdowns | 2 |
| 10. Search and AI visibility | A meaningful change that needs investigation | 3 |
| Total | A weekly triage, not a complete audit | 22 |
Download the free technical SEO toolkit for the workbook, PDF field guide, research library and Claude/ChatGPT tools. You can use the checklist without buying an SEO tool. A crawler becomes useful when checking pages one at a time starts to feel like your entire job.
1) Robots.txt – The Lurking Assassin
Robots.txt is like a skunk – it’s a harmless enough animal that’s actually kind of cute, until it attacks.
It’s a very simple text file found on most any site in the world at your-domain-name.com/robots.txt.
The combination below asks all compliant crawlers covered by the wildcard group to stay out of the site:
User-agent: *
Disallow: /
On a public production site that depends on search, an accidental rule like this can be DISASTROUS! But read the whole file. A rule applies within its user-agent group, and more specific rules can change the outcome. Seeing Disallow: / somewhere in the file does not automatically mean Googlebot is blocked.
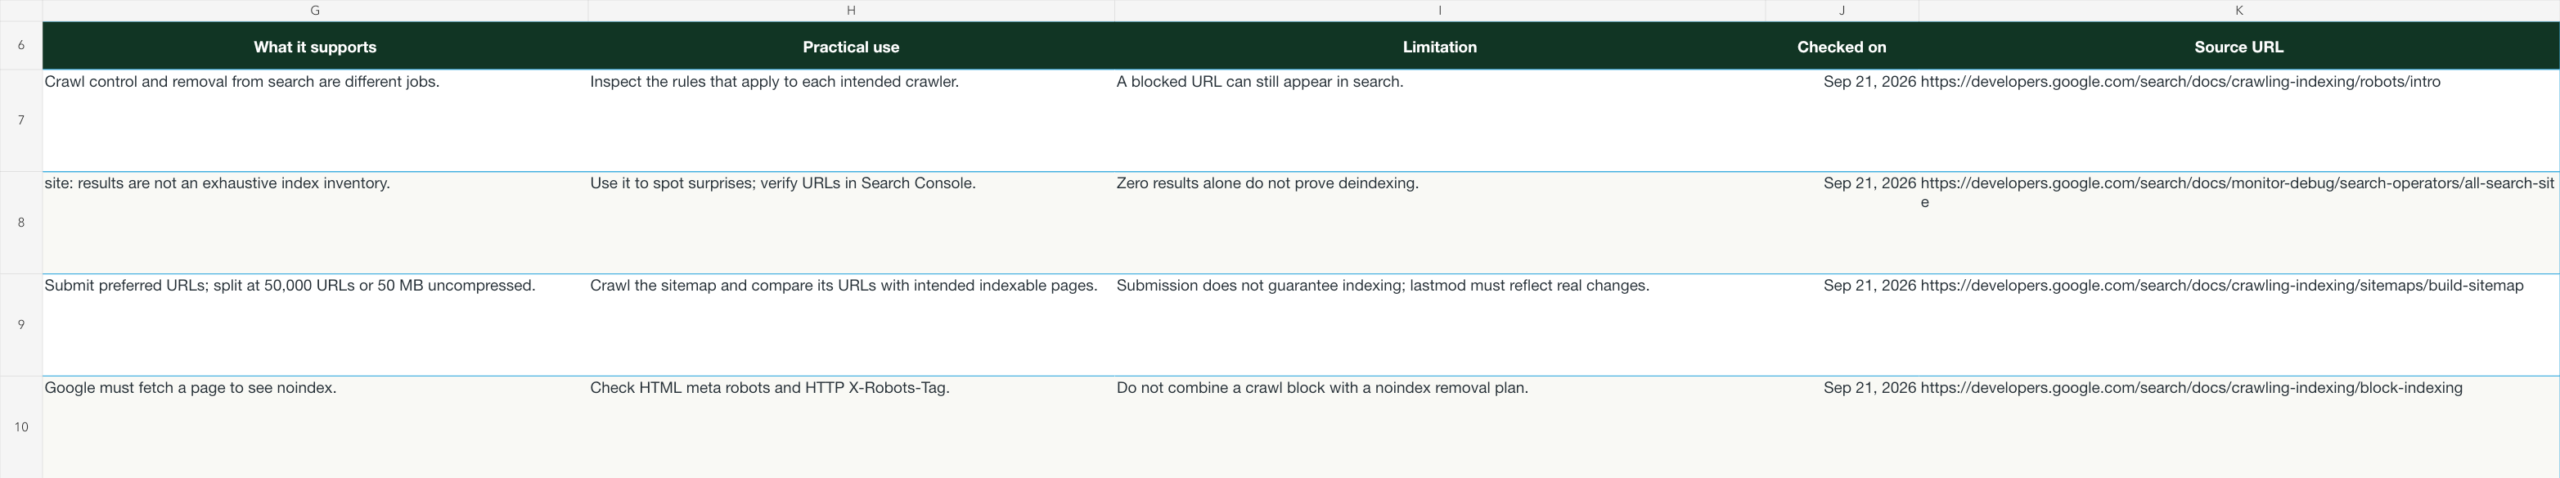
Robots.txt controls crawling. It does not reliably remove a URL from search, and it does not secure private content. Google can sometimes show a blocked URL based on information found elsewhere. Use authentication for private staging environments. Google’s robots.txt guide
Action items:
- Open your robots.txt file and identify the groups affecting your intended search crawlers.
- Test the homepage and one important URL from each major section.
- Check other folders that are blocked – are those correct in being blocked?
- If the file looks fine but requests fail, check the CDN, firewall and server with whoever manages them.
Bonus: the robots.txt file should list your XML sitemap or sitemap index to give search crawlers more direction and crawlability options. It is also possible to submit the sitemap through Search Console.
2) Google “site:” Operator – Useful Detective, Terrible Accountant
It’s a simple command that can instantly tell you a lot about the health of your site in organic search. All you need to do is type in site:yourdomain.com, replacing yourdomain.com with your actual website name.
Do you see strange subdomains such as “dev” or “staging”? Do you see spam or black-hat SEO pages in the results? Those are useful discoveries.
The result count cannot validate your indexed page count. Google explicitly says site: results are not exhaustive. An indexed page can be missing from that search. Zero results deserve investigation, but they are not the diagnosis. Google’s site: documentation
Action items:
- Use
site:for a quick look at unexpected URLs and search appearance. - In Search Console, inspect your homepage, main offer page and a recently updated page.
- Record the indexed status, last crawl and Google-selected canonical.
- If something changed, compare the indexed information with a live test. A live test checks the page now; it does not certify that the current version is indexed. URL Inspection documentation
3) XML Sitemaps – Your Clear Index for Google
XML sitemaps list out all the important pages on your website that you want Google to crawl, as well as last updated information.
Often forgotten, sometimes illuminating, the XML sitemap gives direction to search engines on how to view your pages.
For those with great external linking domains and good internal linking, an XML sitemap isn’t the most necessary component. But as sites get bigger and more complex, an XML sitemap is useful.
A sitemap should describe the pages you want in search. A list full of redirects, deleted pages and URLs you have deliberately noindexed sends a muddled message.
Action items:
- Open the sitemap and any child sitemaps it references.
- Crawl the XML sitemap with a crawler like Screaming Frog to ensure the listed pages are working, intended canonical URLs.
- Check Search Console’s sitemap processing and the indexing of important listed pages.
- Split a file if it exceeds 50,000 URLs or 50 MB uncompressed. Separate sections when that makes diagnosis easier.
- Use truthful
lastmoddates. Regenerating a sitemap is not the same as substantively updating every page.
Submitting a sitemap helps discovery. It does not force indexing. Google’s sitemap guidance
4) Meta Robots – Powerful Enough to Keep You out of the SERPs
The meta robots tag is very powerful and can keep you completely out of the search results. That’s bad when the page is your main service page. It may be exactly what you want for a public page that has no reason to appear in search.
<meta name="robots" content="noindex">
There is also an HTTP response header called X-Robots-Tag. That can carry noindex too, including for files such as PDFs. A plugin setting is only part of the picture.
By default, you do not need to add index, follow to request ordinary indexing behavior. Its presence does not guarantee indexing, and its absence is not an error.
Action items:
- Check the source code and HTTP headers of one important page per template.
- Investigate accidental
noindex, including rules added by the CMS, SEO plugin, hosting or CDN. - Check whether development settings followed the site onto production.
- Remember that Google must be able to fetch a page to see its
noindex. Blocking the same page in robots.txt can prevent that. Google’s noindex guidance
5) Analytics Tracking Code – Can Be Gone in an Instant
Raise your hand if you’ve relaunched a website and a day or two later you check your analytics reporting and your traffic has plummeted. Your heart may sink until you realize the tracking code was simply missing during that period.
We all get busy. But somebody needs to own this check, especially after a redesign, a tag-manager change or a new consent banner.
The 2026 version is bigger than searching the source for a tracking ID. You want to know whether the expected event actually arrives, whether it arrives twice, and whether the lead form still works.
Action items:
- Use Tag Assistant and GA4 DebugView to verify a page view and a test lead event.
- Test the relevant consent states without overriding the visitor’s choice.
- Check your organic search traffic trends in Google Analytics against Search Console clicks over comparable dates.
- Investigate missing or duplicated events before declaring that Google has abandoned you.
Clicks and sessions are different metrics. They should not be expected to match exactly. Google’s analytics verification guide
6) Search Console: Page Indexing, URL Inspection & Crawl Stats
Start with Search Console for Google’s view of a crawling or indexing problem. The old “Crawl Errors” instructions in this article needed retirement.
Use Page Indexing to understand groups of indexed and excluded pages, URL Inspection for an individual URL, and Crawl Stats for crawling and host-availability patterns. Page Indexing, Crawl Stats
You should review and fix the most important crawl errors. If you’re seeing large scale problems, you need to get to the root of the cause.
Not every excluded page is a problem. You may have retired a product, redirected an old article, or deliberately kept a utility page out of search. The useful question is whether an important page is excluded for the wrong reason.
Action items:
- Review new exclusion patterns against your intended page inventory.
- Inspect representative URLs before applying a sitewide fix.
- Investigate broad server failures promptly.
- Redirect a retired page when a relevant replacement exists. If it is truly gone with no equivalent, a proper 404 or 410 can be the correct result. Do not redirect everything to the homepage. Google’s HTTP-status guidance
Check the report date, too. A stale graph is evidence about a reporting period, not a live test of your site.
7) Manual Actions and Security Issues – the Worst of the Worst
Without a doubt, one of the gravest SEO problems is a manual penalty from Google. This means that a manual action was performed by the Google team. It’s simple to detect, but fixing it can mean a world of pain.
Check Manual actions and Security issues separately. If Google reports an issue, read its scope and instructions before changing anything. Manual actions report, Security issues report
An empty Manual actions report does not prove that your site is unaffected by an algorithm update. And a traffic drop is not automatically a manual penalty.
Action items:
- Confirm that the right people receive Search Console notifications.
- Review both reports and save evidence of any reported issue.
- Give security incidents and manual actions a named owner immediately.
- Keep an investigation separate from a rushed list of speculative fixes.
8) Broken Internal Links – Frustrating Humans and Crawlers Since 1994
Broken internal links are bad for both site users and search engine crawlers alike. If the user hits too many broken links on your site they’ll bounce and find somewhere more high quality.
If your site is small enough, you can manually test the links on your site, and you’ll probably find poor grammatical errors as well. For most of us though, this is as painful as pulling teeth. Thankfully there are lots of great tools that can make this easier.
A crawler hitting a 404 is not stopped from crawling your entire site. The practical problem is the broken route to the next useful page.
Action items:
- Use a crawler such as Screaming Frog, Ahrefs Site Audit or Semrush Site Audit to identify broken destinations and the pages linking to them.
- Fix links in navigation and important customer journeys first.
- Update internal links to the correct final destination instead of making visitors travel through avoidable redirects.
- Check that important links are real HTML anchor links with an
href, including links inserted by JavaScript. Google’s link best practices
9) Canonicals and JavaScript – Check What the Engine Actually Gets
Your page can look perfectly fine in your browser while telling a search engine to favor another URL, or while failing to deliver its important content in the version a crawler receives.
The canonical tag tells Google which equivalent page you prefer. Google may choose differently. Consistent internal links, redirects and sitemaps help avoid contradictory signals. Canonical documentation
Glenn Gabe’s 2026 canonical case studies are useful here: a wrong canonical choice can have consequences beyond the familiar Google result. They are cases to learn from, not a promise that every AI system uses the same path.
Action items:
- Compare the declared canonical with the Google-selected canonical on important pages.
- Compare original HTML with rendered HTML. Then use URL Inspection to check Google’s tested page.
- Look for missing descriptions, product facts and links, especially when they require a click or another interaction to load.
- Keep essential content accessible without relying on every bot to execute your JavaScript. Google’s JavaScript guide
A specific 2026 correction: Google documents a 2 MB per-URL fetch limit for Googlebot’s non-PDF resources, with a separate 64 MB limit for PDFs. This is not your total page-weight allowance. Bloated inline code can put important content past the fetched portion. Most ordinary pages will not approach that limit. Google’s March 2026 explanation
10) Core Web Vitals – Make the Page Pleasant to Use
Open your most important page on a phone. Read it. Tap the menu. Fill in the form. A score cannot tell you whether the sales enquiry actually reaches your team.
For Core Web Vitals, use the current metrics: Largest Contentful Paint, Interaction to Next Paint and Cumulative Layout Shift. FID is the retired one.
| Metric | What it checks | Good threshold |
|---|---|---|
| LCP | Main-content loading | 2.5 seconds or less |
| INP | Responsiveness to interaction | 200 milliseconds or less |
| CLS | Unexpected layout movement | 0.1 or less |
These thresholds apply at the 75th percentile, with mobile and desktop considered separately. Use real-user field data where it exists, then lab diagnostics to investigate a cause. No field data means you do not have enough evidence for that assessment. Google’s Web Vitals definitions
Action items:
- Check important page types, not only the homepage.
- Record whether the data describes the URL or the wider origin.
- Investigate big images, slow responses, layout shifts and expensive scripts when the tests point there.
- Retest after the fix. Do not turn chasing a perfect lab score into the total distraction we discussed at the beginning.
11) Structured Data – Useful, Provided It Tells the Truth
Structured data gives machines explicit information about the page. It should agree with what a person sees: the same product, author, price, business and content.
Action items:
- Use markup relevant to the page and a currently supported search feature.
- Validate representative URLs with Google’s Rich Results Test.
- Check the visible facts as well as the validation result.
- Look for conflicting output from plugins and templates. Google’s structured-data policies
One update that changes older checklists: Google retired FAQ rich results in May 2026 and removed that feature’s documentation in June. Keep FAQs that help readers. Stop promising Google FAQ rich results as the payoff for adding them. Google’s documentation changelog
12) AI Search – Check Access, Inclusion and What You Can Measure
The first job is still making useful pages accessible. Google says no special AI schema or llms.txt file is needed for its generative search features. It also says llms.txt does not affect visibility or rankings in Google Search. Google’s AI optimization guide
But there are new things to check in 2026:
- Google’s inclusion setting: inspect the Search generative AI control and whether the property inherits its setting from a parent. Control documentation
- Google’s AI impressions: use the dedicated generative-AI report when it is available for your property. Its impressions are not clicks or revenue. Report documentation
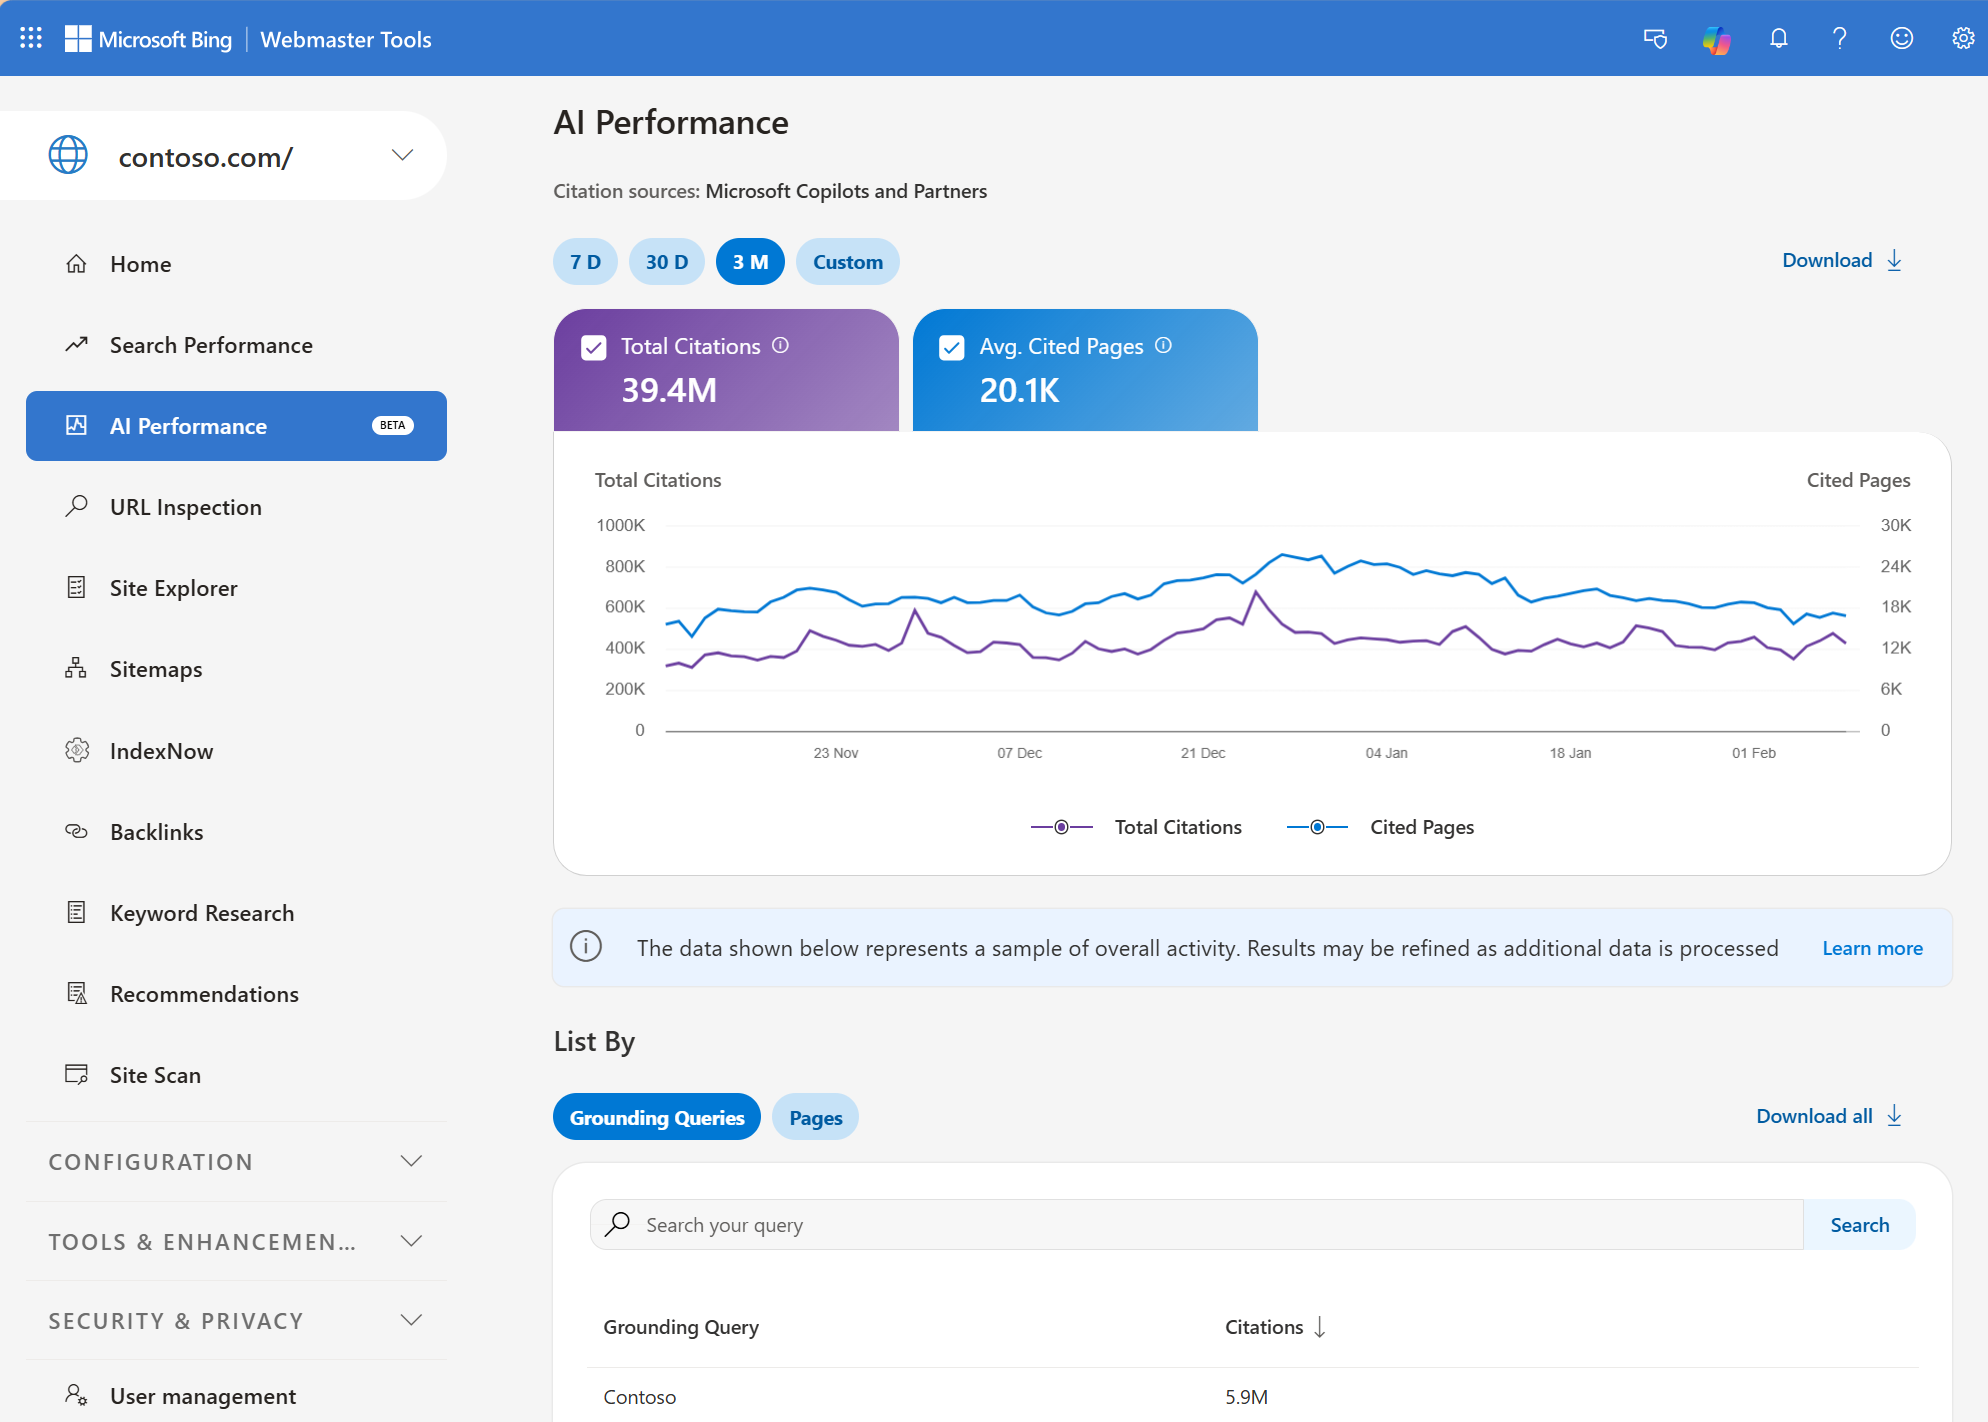
- Bing’s AI citations: review AI Performance in Bing Webmaster Tools for supported experiences. Microsoft’s announcement
- Crawler roles: a decision about model training is not automatically a decision about search access. Review the documented roles of OAI-SearchBot, GPTBot and user-triggered fetching. OpenAI’s crawler guide
- Changed URLs: consider IndexNow for participating engines. Acceptance is a notification receipt, not proof of indexing. IndexNow FAQ
Brave and Yandex belong in the research library, too. Use Brave’s crawler guidance and Yandex’s rendering controls when those audiences matter. Google’s implementation is not a universal specification.
Finally, read the answer that cites you. Is it accurate? Does the link point to the right page? A citation that gets your offer wrong is not an uncomplicated win. Lily Ray’s informal misinformation experiment is a good reminder that a source link is not a fact-check.
BONUS ROUND / AI SEARCH, WITH RECEIPTS
Bonus: AI Search Checks Before You Chase the Next Acronym
You do not need to throw your technical SEO checklist in the ocean. But checking Google alone no longer answers every access question. Use these checks on three important pages before adding another AI visibility tool to the pile.
 ChatGPT
 Claude
 Gemini
 Perplexity
Different platforms, different controls. Use each provider’s current documentation for the system you are checking.
Separate search access from model training
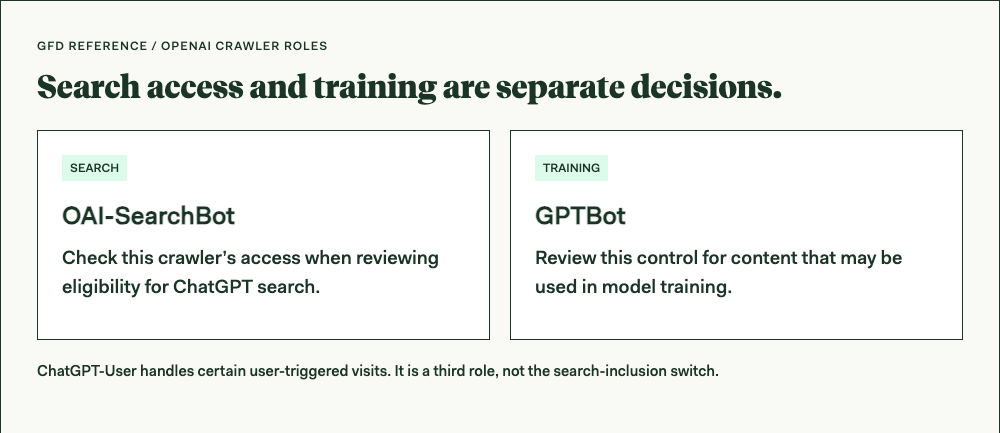
Decide which uses you want to allow. OpenAI documents OAI-SearchBot for search and GPTBot for potential training use; those controls are independent. A ChatGPT-User fetch is a different, user-triggered action. Claude also documents separate search, training and user-request agents. A blanket “block AI bots” rule may do more than you intended. OpenAI crawler roles, Claude crawler roles
Check the front door after robots.txt
An allowed crawler can still hit a firewall challenge, 403 response or rate limit. Ask your developer to inspect verified bot requests in server or CDN logs. Record the URL, time, response and rule involved. Perplexity documents checking both user-agent and published IP ranges when configuring access. Changing a test request's user-agent alone does not prove the real crawler gets through. Perplexity access guidance
Make the useful facts readable
Check whether the main answer, product facts, prices and important links appear in the HTML a fetcher receives. Compare that with the rendered page. Put essential information in accessible text instead of relying entirely on an image, a click or a client-side interaction. Rendering capabilities vary; a successful Google test does not certify every other system. Clear headings help readers, but there is no magic paragraph length that earns a citation. Google's technical guidance for AI search
Give an answer a reliable source to point to
Keep important facts consistent across the page, its structured data and relevant business or product listings. Use stable URLs, clear authorship and truthful update dates. Put the evidence next to the claim it supports. Microsoft recommends clear structure, supporting evidence and current information; none of those is a promise of selection. Bing's guidance
Check the answer, the visit and the lead separately
Save the prompt, engine, date, answer and cited URL for a small set of customer questions. Check whether the answer represents your offer accurately. Repeat observations before calling a change a trend. Use Google's generative-AI impressions and Bing's citation reporting for their stated scopes, then review identifiable referrals and enquiries separately. An impression, a citation and a qualified lead are three different things. Google report definitions
Let AI help with the audit, then check its homework
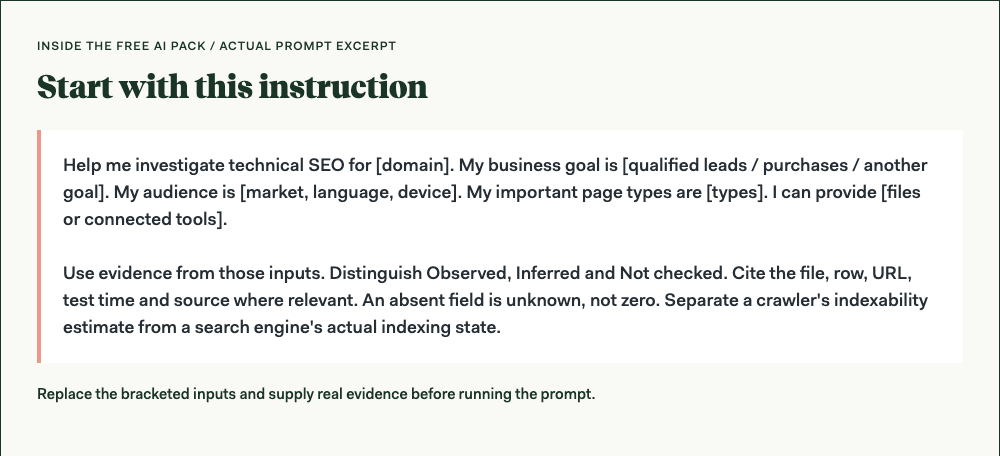
Give the assistant a crawl export, the intended behavior and the relevant evidence. Ask it to group issues, identify missing tests and draft a ticket. Review its proposed change before implementation. A convincing explanation is not proof that it inspected your site.
Try this with the included prompt pack:
Using only the evidence I provide, identify the highest-priority confirmed issue on these three URLs. Separate observations, hypotheses and missing evidence. Draft one implementation ticket with an owner placeholder, acceptance test and rollback. Do not invent crawl results or assume you can access my accounts. If the evidence is insufficient, tell me what to test next.
Keep the original crawl and retest after the fix. Future-you deserves something better than “the chatbot said it was fine.”
Two Original Checks with a Different Job
Linking Root Domains – A Yardstick for Competitors
Linking root domains means the number of different websites linking back to your website. You can quickly compare the number of linking root domains using some backlink checker tools. You should use more than one when possible so you have greater accuracy.
Use this to reverse engineer opportunities and threats for your link building strategy. But the competitor with more referring domains does not automatically win. Relevance, the actual linking pages, the destination content and the wider search context matter.
Put this in the monthly strategy review. It is not the same kind of emergency as accidentally blocking your site.
Ahrefs & Semrush Traffic Value – Show Me the Money
Wouldn’t you love to know if your competitor is earning big bucks from organic search?
Traffic-value estimates can give you a directional comparison of the paid-search equivalent of estimated organic traffic. They cannot tell you the competitor’s actual revenue, profit or lead quality.
You can rapidly plug in different domains and compare them. Just keep the database, location and date consistent. Then come back to your own qualified leads and sales before deciding whether organic search is working for you.
What the Research Changes, and What It Doesn’t
To make this checklist useful on real websites, the research compendium keeps different kinds of evidence separate.
Official documentation tells us how a platform says its controls work. Practitioners such as Glenn Gabe, Shaun Anderson at Hobo, Dan Petrovic at DEJAN AI, Lily Ray and Patrick Stox help identify failure patterns and questions worth testing. Vendor studies can expose useful patterns, but a correlation in their sample is not a setting you can turn on.
For example, Semrush’s technical SEO study describes correlations among cited pages. That is not a reason to migrate working URLs to hit a favored character count. Surfer’s September 2026 authority study does not establish that links are irrelevant, either.
The Google Content Warehouse leak and antitrust materials are valuable context. They are not a complete, current ranking formula. Mike King’s original leak analysis explicitly notes the missing scoring functions and unknown usage. A public trial exhibit discussing Navboost does not tell you to manipulate clicks or treat your GA4 bounce rate as a Google ranking input.
Research papers need the same care. The GEO paper tests an experimental setting. A 2026 critical survey helps explain why retrieval, citation and business outcomes should be measured separately. arXiv hosts research; appearing there is not itself proof of peer review.
The practical priority is to fix verified access and indexing failures, improve the experience on important pages, and test the rest against a business outcome. Keep your curiosity. Keep your receipts, too.
THE TOOLBOX / PICK YOUR NEXT MOVE
Our favorite SEO tools
Nine favorites, three jobs: find technical problems, research opportunities, and measure what happens after the click. You do not need all nine. Pick the tool for the question in front of you.
Screaming Frog
Technical crawler
Intermediate–advanced
Crawling URLs, finding broken links and redirects, and inspecting canonicals and rendered content.
For: SEOs and developers who want detailed evidence and flexible exports.
Explore Screaming Frog
Sitebulb
Guided technical audits
Beginner–intermediate
Explaining crawl findings with prioritized hints and visualizations. Helpful when a wall of crawl data needs a little translation.
For: Marketers learning technical audits and teams presenting findings.
Explore Sitebulb
Ahrefs
Search & backlink research
Beginner–advanced
Researching backlinks, competing pages and keyword opportunities, with site auditing alongside them.
For: Content marketers and SEOs deciding where to compete next.
Explore Ahrefs
Semrush
Research & campaign tracking
Intermediate–advanced
Combining keyword research, competitor analysis, rank tracking and site audits in a broad marketing platform.
For: In-house marketers and agencies managing ongoing search campaigns.
Explore Semrush
Google Search Console
Google search performance
All levels · start here
Seeing Google search clicks and queries, checking index coverage and inspecting individual URLs.
For: Every site owner. Start here before buying a shiny dashboard.
Explore Google Search Console
SEO Gets
GSC + GA4 reporting
Beginner–intermediate
Bringing Search Console and GA4 data into easier-to-scan dashboards, with views across multiple websites.
For: Site owners and agencies tired of hopping between properties.
Explore SEO Gets
Google Analytics 4
Website & app analytics
Beginner reports · intermediate setup
Connecting acquisition channels with on-site activity and key events, such as an enquiry or purchase.
For: Marketers asking what visitors do after they arrive. Check the tracking first.
Explore Google Analytics 4
Amplitude
Product & behavioral analytics
Intermediate–advanced
Investigating funnels, user journeys and retention to find where people get stuck or return.
For: Product and growth teams, especially SaaS. More useful once events are well defined.
Explore Amplitude
Detailed SEO Extension
Quick browser inspections
Beginner–intermediate
Checking a page’s metadata, heading structure and indexing signals right in Chrome.
For: Writers, marketers and SEOs doing a quick spot check between full audits.
Explore Detailed SEO ExtensionYour first setup: New here? Start with Search Console, Detailed for quick page checks, and a correctly configured analytics tool. Add one crawler when you need to investigate the whole site. Choose Ahrefs or Semrush when research becomes a regular job; try the workflow before paying for both.
Skill levels are our suggested starting points, not prerequisites. GA4 and Amplitude measure behavior; they do not diagnose crawlability. Features checked September 21, 2026; each card links to the provider.
What’s Next?
Technical SEO means different things to different people.
A small startup SaaS site with 10 pages can do the basics while it focuses on growth. Massive, multi-million-page sites with new data refreshes daily, and heavy competition need a whole team monitoring and updating technical SEO issues weekly.
Depending on what problems you’re trying to solve, use the above resources to dig in further and prioritize your problems for the next quarter.
Start with the free workbook. Pick three important pages, record what you actually checked, and give the highest-impact confirmed problem an owner. The field guide walks a team through that first review, and the AI pack helps organize findings and write implementation tickets.
When the problem reaches across templates, requires a migration, or depends on how the site renders, we can help with technical SEO consulting. For an example of the coordination involved, see our Rustici Software migration and relaunch work.
LEVEL 2 THE IMPLEMENTATION SPRINT KIT
Found the bug?
Let’s get the fix out the door.
Level 1 helps you find and prioritize issues. This kit helps you give the gremlin a ticket, an owner and a test it has to pass.
Your Level 2 loadout
- 6 worked examplesSee how a confirmed issue becomes a scoped fix with acceptance and rollback steps.
- Editable handoff templatesA developer ticket and stakeholder brief, ready for your actual evidence.
- A plan through the retestA 30-day plan, sprint backlog and release/retest trackers. Keep “shipped” and “verified” separate.
Free self-service templates. Examples are hypothetical; a bespoke audit or done-for-you fix is not included.
Get the free Level 2 kit
Fill in the form and your ZIP download appears immediately. No meeting required.
We use these details to provide the resource and understand your website. This form does not sign you up for a newsletter.
Form not loading? Open the download form.
Update Log
The weekly-checkup approach also appeared in Joe’s 2022 Search Engine Journal article. The controls and reporting described here have been updated for 2026.
- September 21, 2026: Rebuilt the weekly triage, corrected legacy reporting and indexing advice, added canonical/rendering checks, current AI-search controls and reporting, and a downloadable workbook and AI pack. Added practical AI-search bonus checks, the favorite-tools grid and the Level 2 implementation offer.
- July 16, 2024: Fixed grammatical issues and other clarifications added.
- Nov 23, 2023: Updated throughout.
- 2020: Released as this blog post.
- 2017: First created as PDF.
Case study · Technical SEO
+13 DR
after relaunching three sites at once
Rustici Software folded SCORM.com and xAPI.com authority into one domain and kept organic traffic steady.

Leave a Reply